Blog Post
Meeting the NIST AI RMF Measure Function With Monitoring Evidence
October 26, 2026
Measure carries four categories and twenty-two subcategories, and they divide cleanly by what kind of evidence satisfies them. Some ask whether something was observed. Others ask whether something was tested. Monitoring answers the first group and contributes almost nothing to the second.
the AI RMF Core describes the function as employing quantitative, qualitative or mixed methods to analyze, assess, benchmark and monitor AI risk, with systems tested before deployment and regularly while in operation. The split between those two activities is the one that decides what an operational record can carry.
Which Outcomes Does Monitoring Satisfy Directly?
Five, concentrated in the categories about production behavior and risk tracking.
Production Monitoring Under Measure 2.4
The subcategory asks that the functionality and behavior of the system and its components be monitored when in production. Activity records answer it directly, since the obligation is to observe rather than to evaluate.
Risk Tracking Under Measure 3.1 and 3.2
Approaches, personnel and documentation have to be in place to identify and track existing, unanticipated and emergent risks based on intended and observed performance in deployed contexts. Monitoring supplies the observed-performance half, and 3.2 asks for tracking approaches where measurement techniques are not yet available, which is where observed behavior substitutes for a metric.
Security and Resilience Under Measure 2.7
Evaluation and documentation of system security and resilience draws on enforcement outcomes, blocked actions and incident records that accrue from operating. An inventory recording which sources detected each asset supplies the coverage position that evaluation rests on.
Which Outcomes Need Testing Instead?
Most of Measure 2, where the subject is the model's own properties rather than its behavior in use.
The Testing Subcategories
Measure 2.5 requires demonstrating validity and reliability with documented limits on generalizability. Measure 2.11 requires fairness and bias evaluation. Measure 2.9 requires the model to be explained and validated. None is answerable from records of what the system did, because each asks what the system is.
Why Observation Cannot Substitute
A system can behave acceptably across every observed interaction while carrying a bias that no observed interaction surfaced. Evaluation requires held-out cases and a comparison against something known, which is a different activity from watching production traffic.
What Covers Them
Test sets with documented metrics under Measure 2.1, red teaming, and independent assessment. Adversarial testing sits here rather than in the monitoring column.
Which Outcomes Need People?
A third group, satisfied by neither monitoring nor testing, which is the part most readers overlook.
Independent Review Under Measure 1.3
Internal experts who did not serve as front-line developers, or independent assessors, have to be involved in regular assessments. The outcome is about who performed the work rather than what the work found, so no artifact satisfies it without the right person having produced it.
Consultation Under Measure 4.1 and 4.2
Measurement approaches have to be connected to deployment context and informed through consultation with domain experts and end users, with results validated by input from relevant actors. These are records of conversations rather than records of systems.
Feedback Channels Under Measure 3.3
Processes for end users and impacted communities to report problems and appeal outcomes have to exist and feed back into evaluation metrics. Building the channel is the obligation, and monitoring only records what arrives through it.
What Does the Split Look Like Overall?
Roughly a quarter observational, half evaluative and a quarter procedural, which is worth stating before a program claims the function is covered.
- Observational: Production behavior, risk tracking and security records, satisfiable from operating systems.
- Evaluative: Validity, safety, explainability, privacy, fairness and environmental impact, each requiring testing.
- Procedural: Independent review, expert consultation and feedback channels, requiring named people and documented processes.
Why the Proportion Matters
A monitoring deployment reported as Measure coverage overstates by roughly three quarters. Stating the proportion in advance is what prevents that claim being made and then withdrawn under questioning.
What Makes the Observational Group Credible?
Documentation of what was not measured, which Measure 1.1 asks for explicitly and most programs skip.
The Requirement
Approaches and metrics are selected starting with the most significant risks, and the risks or trustworthiness characteristics that will not or cannot be measured have to be properly documented. The second clause is an obligation to record the limits rather than only the coverage.
Why It Strengthens the Rest
A program stating what it cannot measure is more credible on what it can, and the statement is itself a satisfied subcategory. Questions that make the framework defensible works the same ground from the assessor's side.
What Should Be Established?
Three things, and the first is a mapping exercise rather than a technology decision.
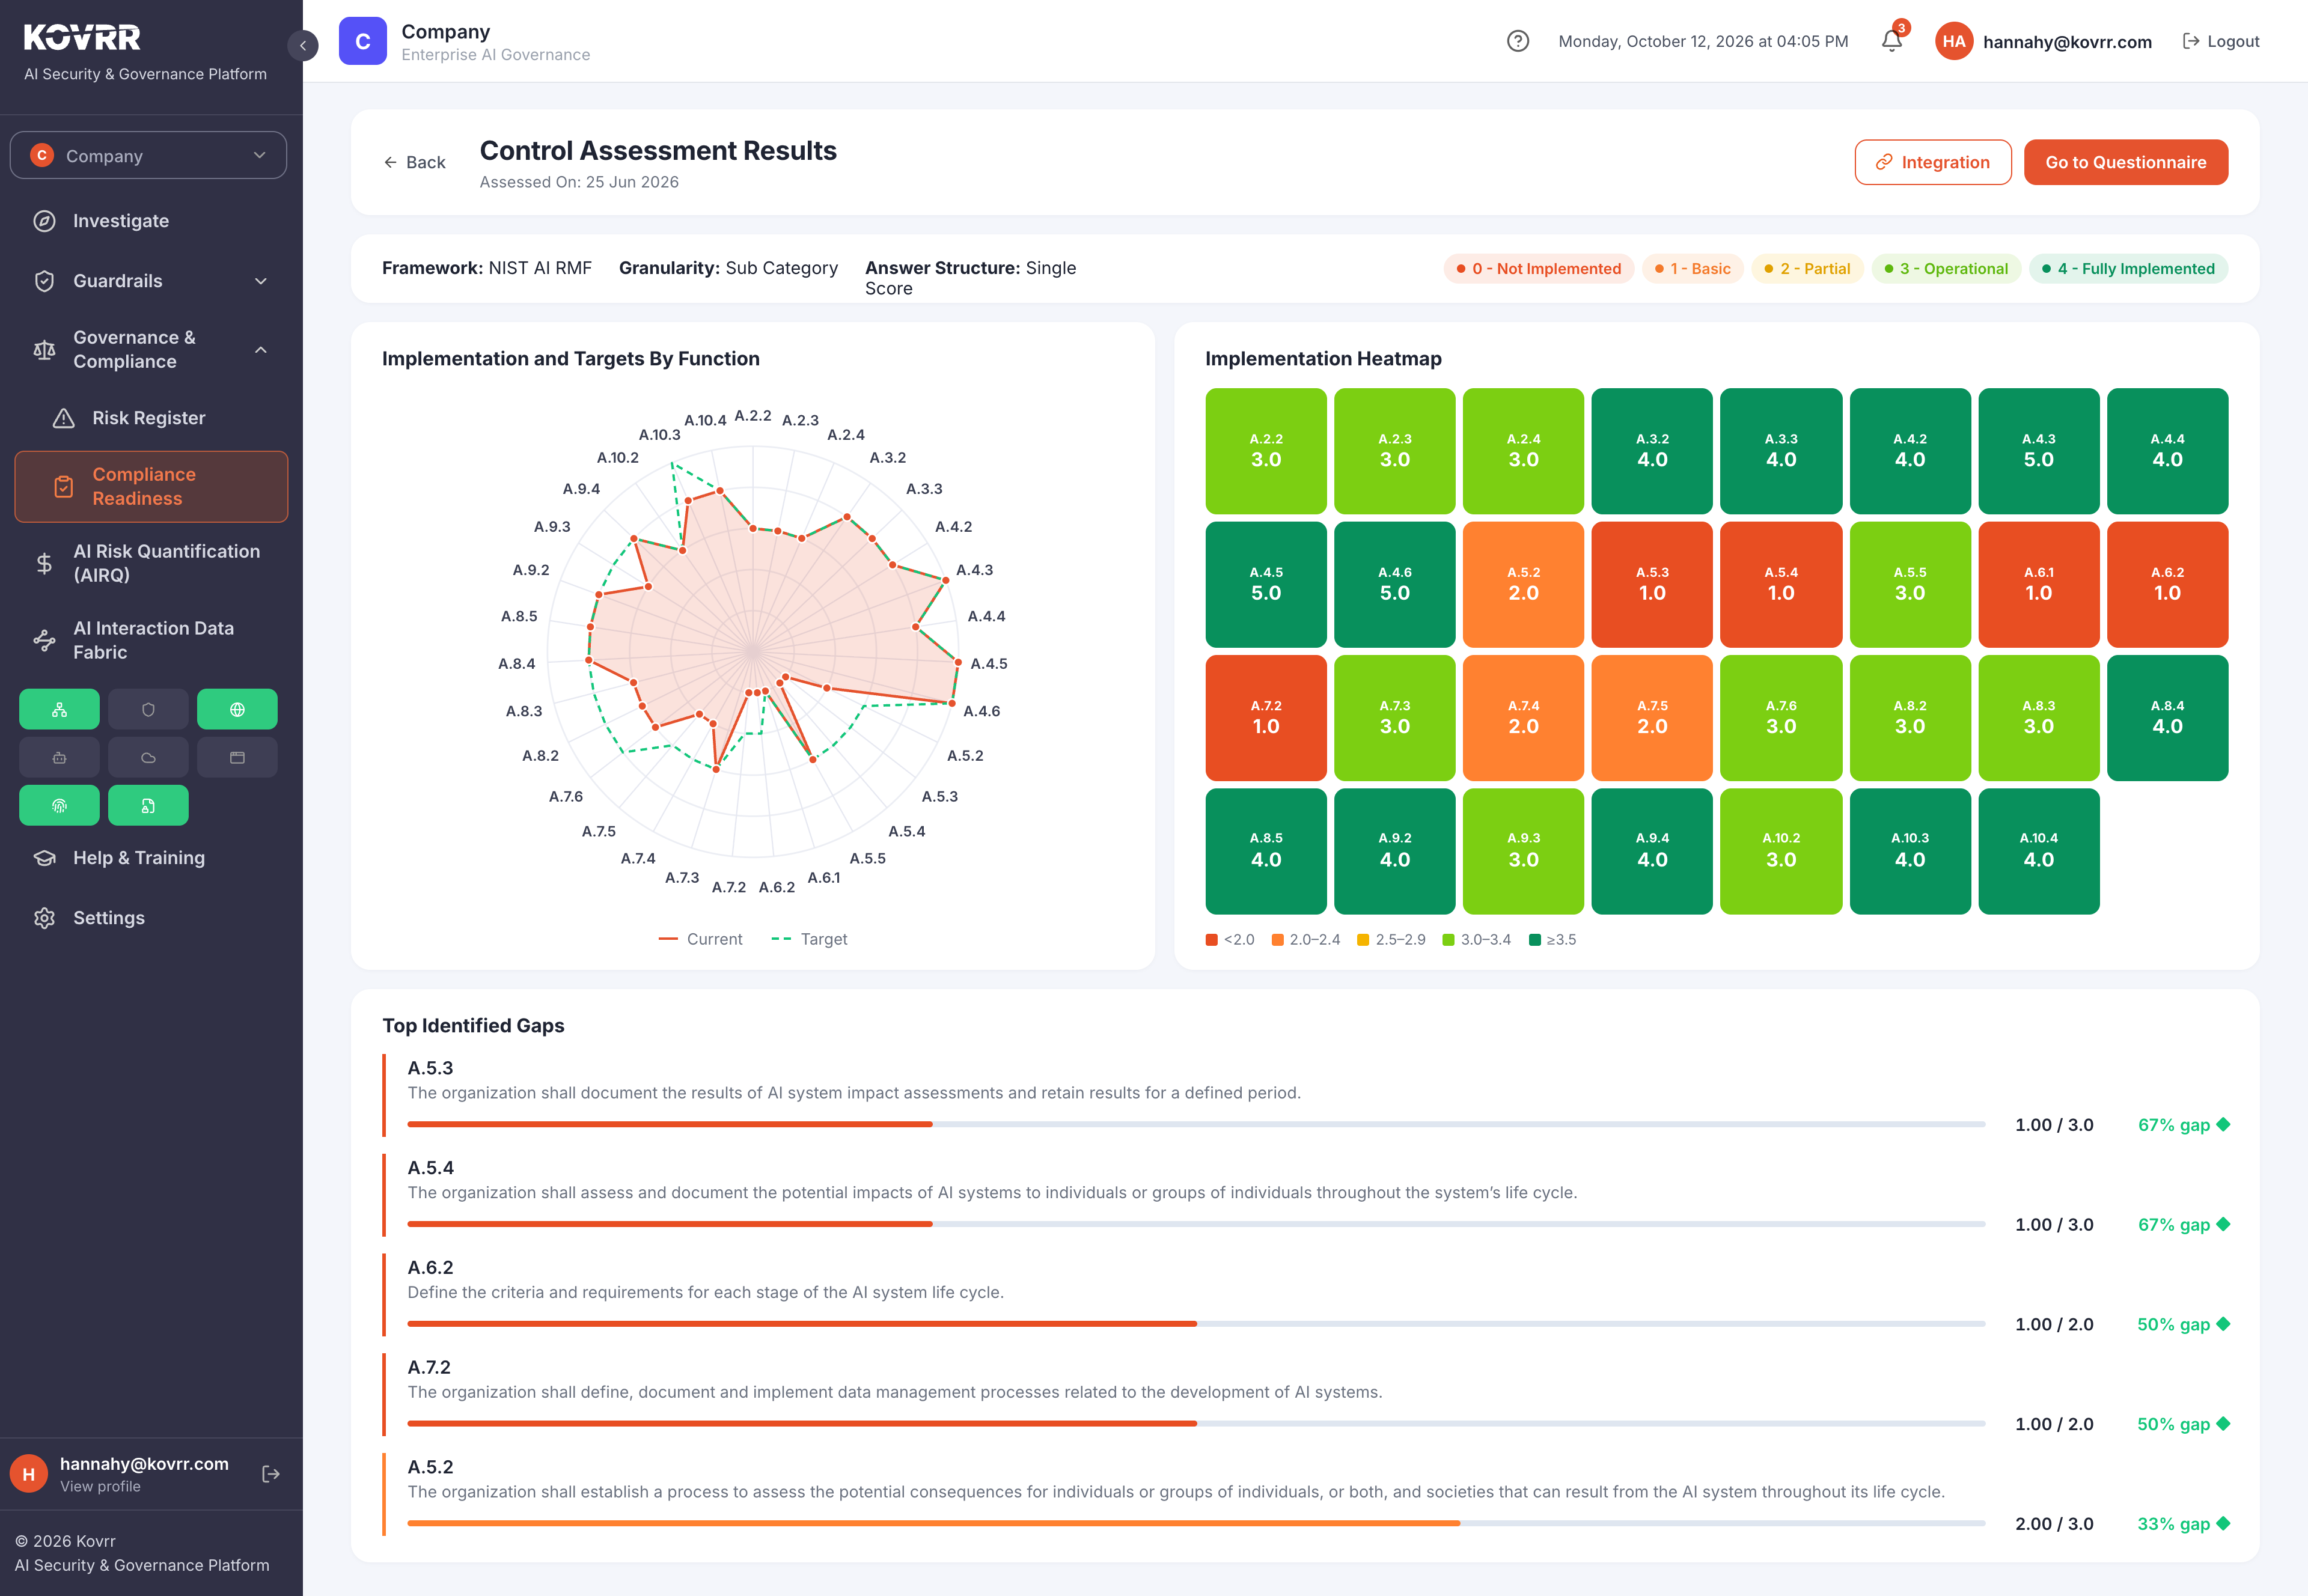
Which of the twenty-two subcategories your current records would evidence, marked individually rather than by category, since the categories are not uniform. Which testing program covers the evaluative group, because monitoring will not reach it. Then whether the risks you have chosen not to measure are documented, since Measure 1.1 requires it and the documentation strengthens every other claim. Kovrr's AI Security and Governance Platform produces the observational evidence with the sources that carried each finding, and the framework is worth reading in full before any mapping begins.
A Quarter of Measure, Answered Well
The function carries four categories and twenty-two subcategories, and they divide by evidence type rather than by subject. Production behavior under Measure 2.4, risk tracking under 3.1 and 3.2, and security and resilience under 2.7 are answerable from records that operating systems produce. Most of Measure 2 asks what the system is rather than what it did, so validity, fairness, explainability and privacy need test sets and held-out cases that no volume of production traffic substitutes for. A third group needs people, covering independent review under 1.3, expert consultation under 4.1 and 4.2, and feedback channels under 3.3. Measure 1.1 also requires documenting what will not or cannot be measured, which is the subcategory that makes the others credible.
To see which Measure outcomes your existing records already evidence, book a demo mapped to your own estate.
NIST AI RMF Measure FAQs
Speak to an ExpertWhat does the NIST AI RMF Measure function cover?

Which Measure subcategories can monitoring evidence satisfy?
Which Measure outcomes cannot be satisfied by monitoring?
Which Measure subcategories require people rather than evidence?
Why does Measure 1.1 matter more than it appears?
How much of the Measure function can an AI monitoring platform cover?