Blog Post
How to Monitor What Data Employees Share With AI Tools
October 19, 2026
Four categories account for most of what leaves an organization through an assistant. Source code, customer records, financial material and credentials. Each announces itself differently, and the differences decide what can be detected from the text alone and what has to be tracked from where it came.
Ordered by how loudly they announce themselves, credentials sit at one end and financial material at the other. Detection moves from reading the content to knowing its origin as you travel down the list.
Credentials Announce Themselves
The easiest category and the only one where the right action is never in doubt.
What Reveals Them
High-entropy strings carrying recognizable prefixes. Key formats are deliberately distinctive so providers can identify and revoke their own credentials, which makes them equally identifiable to anything watching the input field.
Why the Action Is Simple
No legitimate workflow requires pasting a live key into an assistant. False positives are rare and the cost of a block is near zero, so this is the one category where a hard stop produces no circumvention worth worrying about.
Source Code Is Recognizable but Noisy
Detectable from structure rather than from any dictionary, which makes finding it easy and deciding about it hard.
What Reveals It
Syntax patterns, bracket density, indentation and language keywords identify code without knowing anything about the codebase. Tracing it back to a specific repository requires lineage from the editor the block was copied out of.
Why Detection Alone Is Insufficient
Pasting code into an assistant is the single most common legitimate use in an engineering organization. A rule that fires on code fires constantly, so the useful signal is code carrying proprietary markers, meaning internal package names, internal hostnames or license headers.
What Follows for Policy
Warning rather than blocking, with the proprietary markers as the escalation. Device-level coverage matters most here, since a coding assistant inside an editor never passes a browser or a gateway.
Customer Records Are About Shape
The pattern identifies a field and the shape identifies an export, which is the distinction that separates a question from an incident.
What Reveals Them
One email address in a prompt is somebody asking for help drafting a reply. Four hundred rows with consistent column structure is a database extract. The pattern is identical and the structural repetition is what carries the meaning.
Why Pattern Matching Is Not Enough
Simple expression matching counts occurrences without reading context, so it cannot tell the two apart. Local classification that considers the surrounding text decides whether a block constitutes a record set, and AI data leakage at volume looks nothing like the same thing at single-record scale.
Which Changes the Threshold
Record count rather than record presence. A policy expressed as any personal data triggers on ordinary work, while one expressed as structured personal data above a row count triggers on extraction.
Financial Material Announces Nothing
The hardest category, because the text carries no distinguishing property at all.
Why Content Inspection Fails
Numbers look like numbers. A quarterly revenue table, a pricing model and a public statistic share every textual characteristic, so no classifier reading the paste in isolation can separate them.
What Reveals It Instead
Origin. Where the text came from a document inside a protected system, lineage carries the classification forward even after the content is reformatted or aggregated. The signal attaches to provenance rather than to the characters.
Which Requires a Different Source
Identity and application records establish which systems a person had open, so a paste shortly after an export from a finance platform reads differently from the same text with no such history. Reading signals from several sources against one identity is what makes that inference available.
Why Does Conventional Data Loss Prevention Miss This?
Because it was built around documents, and a prompt is not one.
The Architectural Reason
Conventional tooling watches static objects crossing predictable boundaries, covering mail attachments, file transfers and managed shares. A paste into a browser field is neither an object nor a boundary crossing, so the mechanism that decides never engages.
What Is Missing From a Paste
A filename, an extension, metadata and any classification label inherited from a file server. Everything conventional tooling uses to reach a decision is absent, leaving only the characters themselves.
Three Further Blind Spots
- Personal accounts: A permitted domain reached under a personal login looks identical to sanctioned use.
- Desktop applications: Clients that pin certificates sit on an inspection bypass list by design.
- Local models: Inference running on the machine produces no traffic to inspect at all.
What Does In-Page Classification Change?
The position, which changes both what can be seen and how much has to be collected.
Where It Runs
Inside the browser, against composed content before transport encryption applies. The classifier reads what the person assembled rather than what a file contained, which is the form the material takes in practice.
What Leaves the Device
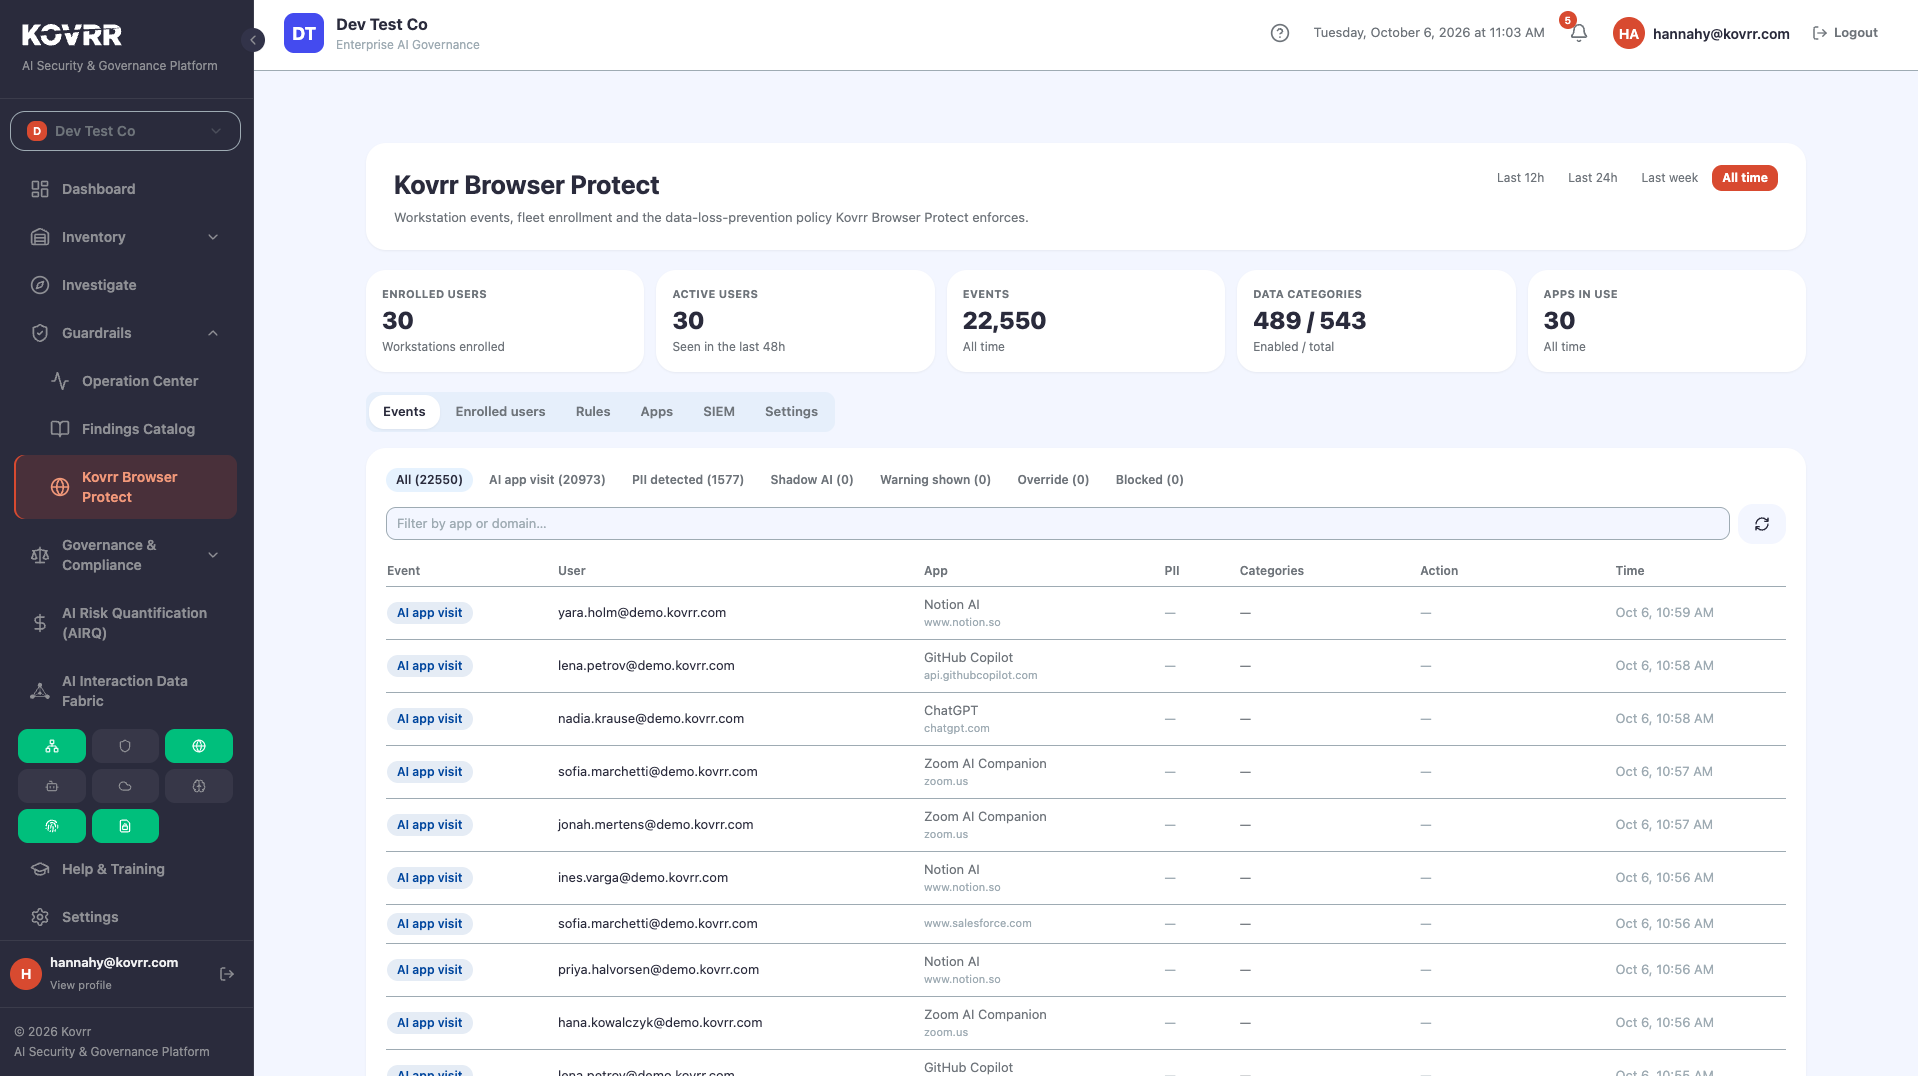
A category identifier, a severity, the action taken and a timestamp. Prompt text, attachments and keystrokes stay where they were. The architecture cannot capture content, which is a stronger position with a works council than a policy of not looking at it.
What It Still Misses
Anything outside a browser on a managed device. Browser-level enforcement covers web applications and personal accounts, and desktop clients need endpoint signals alongside.
What Should Be Established?
Three things, and the first takes an afternoon.
Which of the four categories your current tooling would detect in a browser paste, tested rather than assumed, since the answer is frequently only credentials. Whether personal data policy is expressed as presence or as a record count, because the first fires on ordinary work. Then whether any source records what a person had open before a paste, since financial material is detectable no other way. Usage monitoring supplies the record, and how regulated data leaves one paste at a time covers what accumulates when nothing does.
Content Detects Three, Origin Detects the Fourth
Four categories carry most of what leaves through an assistant, and they announce themselves very differently. Credentials are high-entropy strings with recognizable prefixes, detectable from the text with near-zero false positives and blockable without circumvention. Source code is recognizable from structure alone and so common in legitimate use that proprietary markers rather than code itself are the signal. Customer records turn on shape rather than pattern, since one address is a drafting question and four hundred structured rows is an extract. Financial material announces nothing at all and is detectable only through provenance. Conventional data loss prevention misses all four in a browser because it decides on filenames, extensions and labels, none of which a paste has.
To see which data categories your current controls detect at the moment of sharing, book a demo mapped to your own estate.
Monitoring AI Data Sharing FAQs
Speak to an ExpertWhat data categories should AI monitoring detect?

Why are credentials the easiest category to detect?
Why is detecting source code in prompts difficult?
How do you tell a customer record from a database export?
Why can't content inspection detect financial data?
Why does conventional DLP miss data pasted into AI tools?