Blog Post
What Is an AI Data Fabric?
October 12, 2026
The phrase carries two meanings that point in opposite directions, and anybody searching it will meet both without being told they are different. In one, AI consumes the fabric. In the other, AI is what the fabric watches.
The established meaning belongs to data management. The newer one belongs to AI governance, and it describes a layer that collects signals about AI activity from every connected source and reads them in sequence. This piece defines both and then develops the second.
What Does the Established Term Mean?
A data fabric in the data management sense is an architecture for connecting data across distributed environments without physically moving it. SAP describes its version as the trusted knowledge core for every enterprise application and AI agent, and the technical components are consistent across vendors, built on active metadata, semantic models and virtualization that let consumers find and use data where it already lives.
The Subject Is Business Data
Customer records, transactions, inventory, the material an organization runs on. The fabric makes that material discoverable and consistent across systems that were never designed to agree with each other.
The Consumer Is Increasingly AI
Vendors in this space now position the architecture as the foundation for agentic systems, since a model grounded in governed data behaves better than one grounded in whatever it was handed. The framing is where the phrase AI data fabric comes from, and the AI in it describes who reads the output.
What Does the Governance Sense Mean?
A layer that collects signals about AI activity from every connected source, normalizes them onto shared identifiers, and makes a sequence of events readable as one interaction. The subject is the AI rather than the data it touched.
The Subject Is Behavior
Which identity reached which AI tool, what category of content went with it, what the tool did next, and which other systems the same identity touched around the same moment. None of that is business data in the earlier sense, and none of it lives in one place.
The Consumer Is a Governance Function
Security operations, compliance, risk. People who need to answer what happened and under whose account, usually on somebody else's deadline. The fabric exists so the answer can be assembled from records rather than reconstructed from memory.
Why Does AI Activity Need Its Own Layer?
Because the individually innocuous nature of each signal is the whole problem. A sign-in succeeds. A connection reaches a domain nobody has blocked. A paste happens inside a browser. Each one is ordinary work, and no single source has grounds to raise anything.
The Finding Exists Between Sources
The three together, inside a short window and under one identity, describe a person moving regulated material into an unmanaged account. The finding has no home in any of the three systems that observed a part of it, which is why a layer above them is a structural requirement rather than a convenience.
Which Makes the Join the Capability
Collecting more sources improves nothing if they cannot be read against each other. What determines whether correlation is possible is the identifier the sources share, and the join rather than the sensors is the thing to evaluate.
What Does the Layer Have to Do?
Three functions, and a product missing any one of them is a collection of integrations rather than a fabric.
- Normalize identifiers: Resolve device, account, token and session references from each source onto one subject.
- Preserve sequence: Keep ordering and timing intact, since many findings depend on what followed what.
- Retain provenance: Record which source supplied each element, so a finding can be traced back and challenged.
Why Provenance Matters Most Later
A finding presented without its sources cannot be examined by anybody who did not build it. Retaining which source carried which element is what lets a reviewer ask whether the conclusion holds, and the questions a telemetry claim has to survive all depend on that record existing.
What Is It Not?
Three adjacent things it gets confused with, each sharing some mechanics and answering a different question.
Not a Log Aggregator
Collecting events into one store is necessary and insufficient. A search index answers questions somebody already knows to ask, while a fabric produces findings from relationships nobody queried for.
Not an Observability Stack
Application telemetry measures how a system performs, tracking latency, errors and throughput for software a team operates. The governance sense measures what people and agents did with AI, which is a different question about different subjects.
Not a Gateway
A proxy in the traffic path enforces policy on what passes through it and sees nothing that does not. A fabric observes from many positions at once without needing to sit in the path of any of them.
How Would You Recognize One?
Look at what it can produce rather than what it collects, since every product in this space collects something.
A Finding That Needed More Than One Source
The strongest test available. Ask to see one, then ask which sources carried it and which contributed nothing. A layer that resolves identifiers can answer both parts.
A Coverage Position by Category
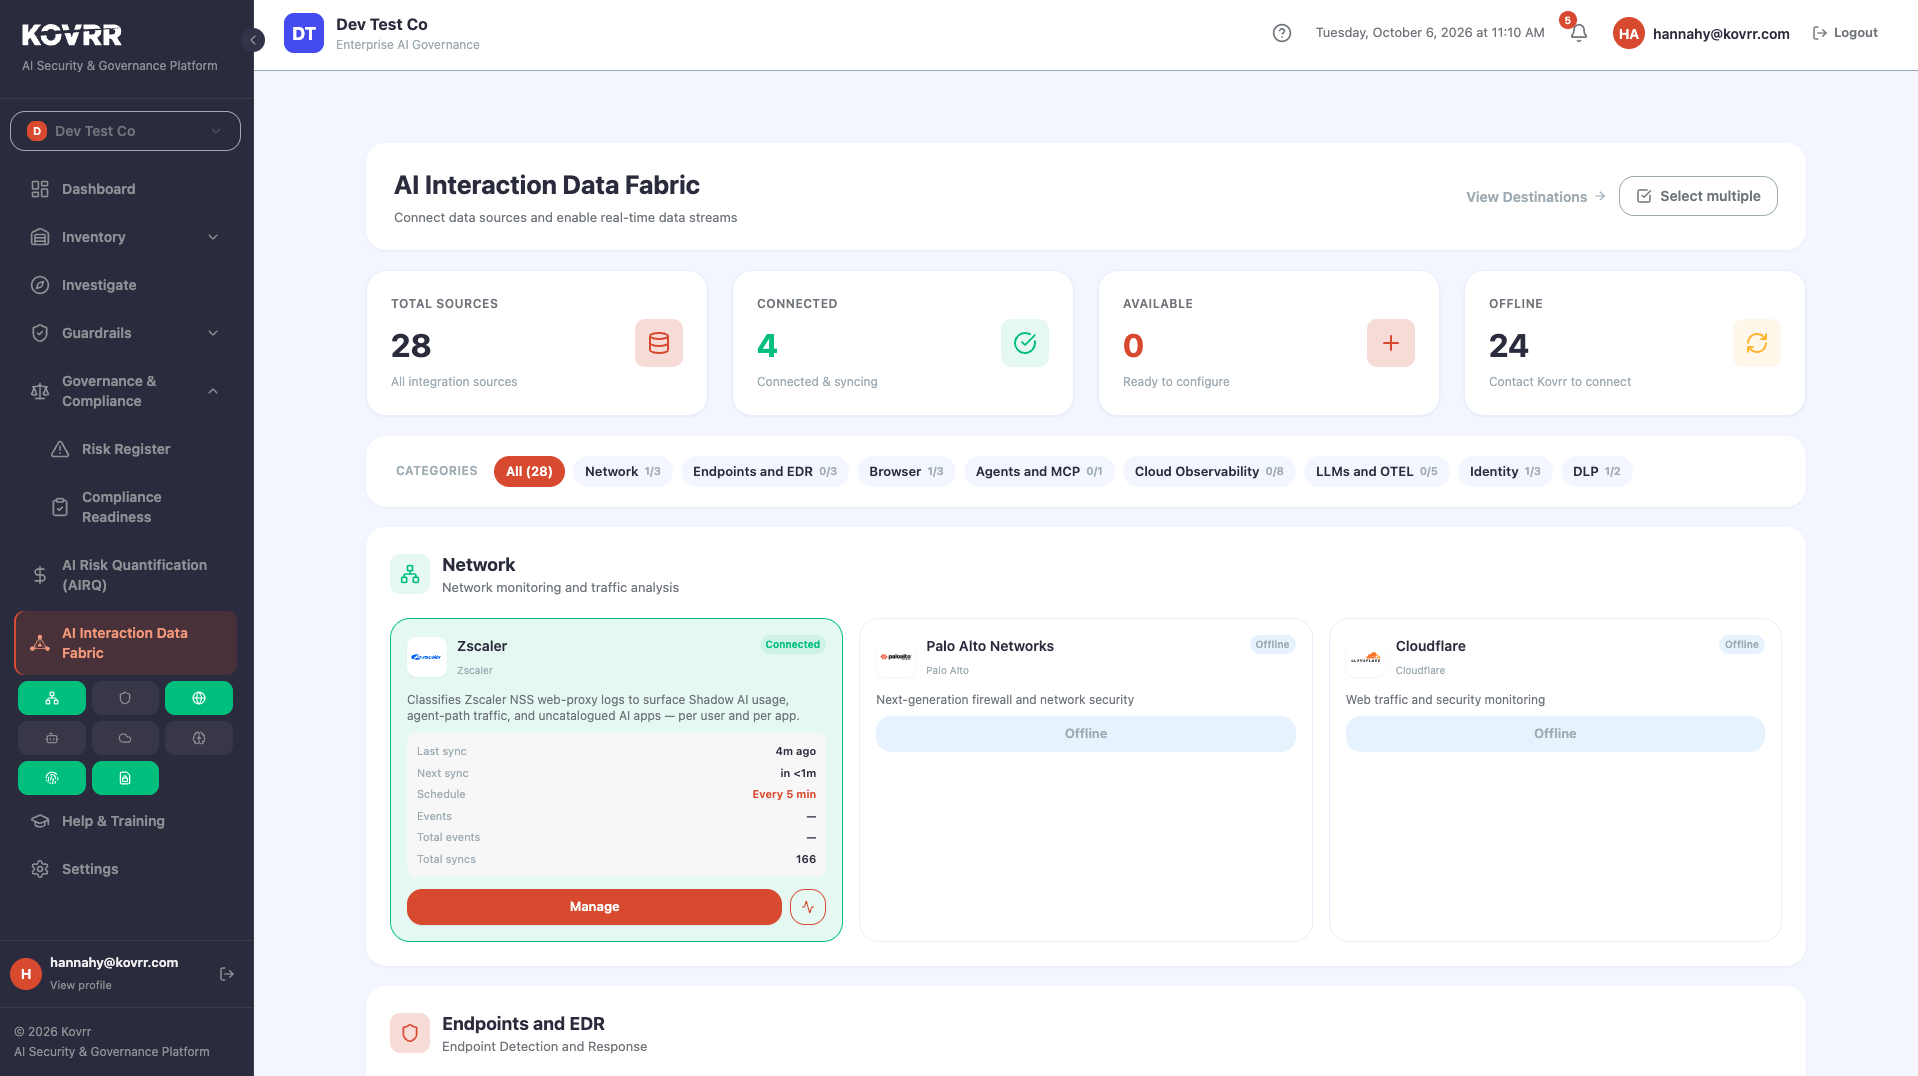
Connected sources against available sources, per surface, so the blind spots are stated rather than discovered. Categories at zero are categories the layer does not observe, whatever the integration catalog offers.
An Answer About Its Own Limits
A fabric reads what its sources supply and nothing else, so the honest version names what falls outside. Building an inventory from observed activity works through what that produces in practice.
How Does Kovrr Build It?
Kovrr's implementation is the AI Interaction Data Fabric, which draws from eight source categories and resolves them onto shared identifiers before any detection rule runs.
What Sits on Top
Findings carry the sources that produced them, and the same records feed asset inventory, policy enforcement and AI risk quantification (AIRQ). The layer is the foundation rather than a feature, which is why the platform is organized around it.
Why the Name Is Specific
Interaction is the operative word. The subject is the exchange between a person or an agent and an AI system, which is narrower than data in general and broader than any one tool's own logs.
Two Fabrics, Opposite Directions
In the data management sense, a fabric unifies business data so AI can use it, built on active metadata and semantic models that let consumers find data where it lives. In the governance sense, a fabric unifies signals about AI activity so an organization can see it, with behavior as the subject and a security or compliance function as the reader. The second exists because each signal is ordinary alone and only becomes a finding when read against the others, which makes the layer a structural requirement rather than a convenience. Recognizing one means asking for a finding that needed more than one source and a coverage position by category. Kovrr's AI Interaction Data Fabric draws from eight categories and resolves them before any rule runs.
To see findings that carry the sources behind them, book a demo mapped to your own estate.
AI Data Fabric FAQs
Speak to an ExpertWhat is an AI data fabric?

How is an AI data fabric different from a data fabric?
Why does AI activity need its own data layer?
What does an AI data fabric have to do?
Is an AI data fabric the same as a log aggregator or a gateway?
How do you recognize an AI data fabric in a product?